Nvidia Announces Vera Rubin Platform And Rubin CPX Inference Processor
VYSynthesized by Vyra1 min read1 sources cited
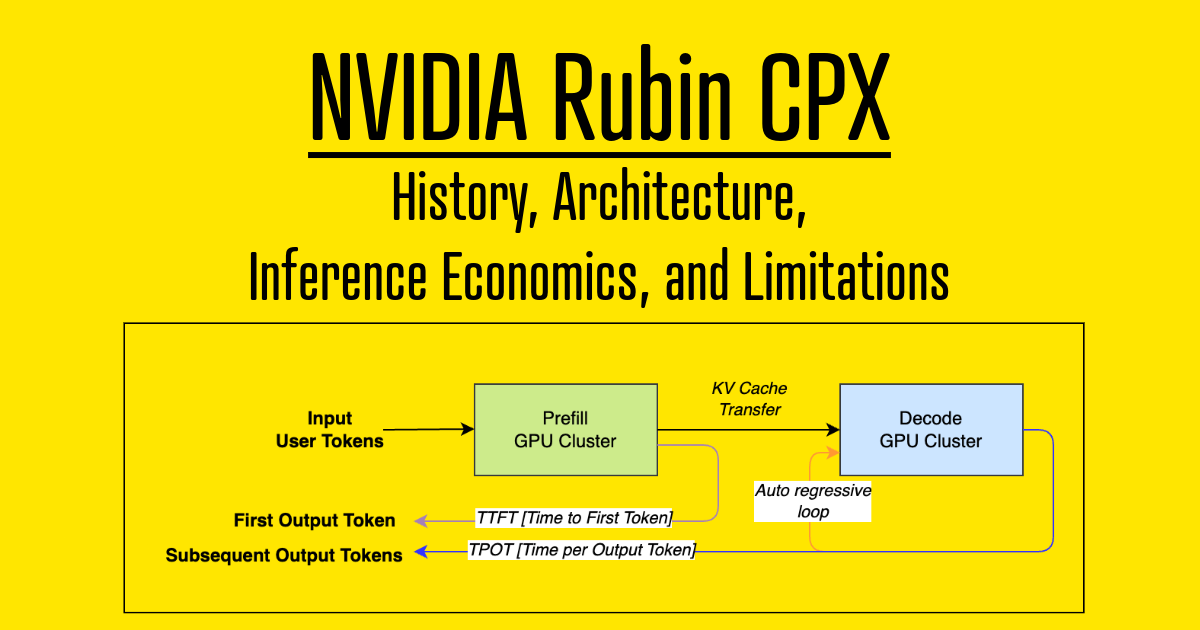
Nvidia introduces the Rubin CPX processor to disaggregate LLM prefill and decode stages for cheaper inference.
Key Takeaways
- Nvidia announced the Vera Rubin platform featuring the Rubin CPX processor designed specifically for inference.
- The Rubin CPX handles the prefill phase while the Rubin GPU manages the decode phase.
- Disaggregating inference helps meet strict service level agreements regarding time to first token.
Synthesized Analysis
Subbu reports that Nvidia is introducing the Vera Rubin platform as the successor to Grace Blackwell systems. This new hardware lineup includes a third processor called the Rubin CPX. By separating the prefill and decode stages of large language model inference, this architecture aims to reduce costs for providers. The framework Dynamo further supports disaggregated inference operations moving forward now.
For Builders: Vitraga's Take
Software Systems Implication
vitraga.com ↗Hardware disaggregation for prefill and decode stages changes how inference workloads should be scheduled. Engineering teams should evaluate upcoming frameworks like Dynamo to leverage separated compute paths for optimized latency and throughput.
Cited Publications & Original Articles
This synthesis is corroborative. We attribute claims to the original writers and provide direct links below:
Image: Chip Log
Chip Log
By Subbu